Rush Hour for Credentials: Borrowing Traffic Models to Predict Access Load
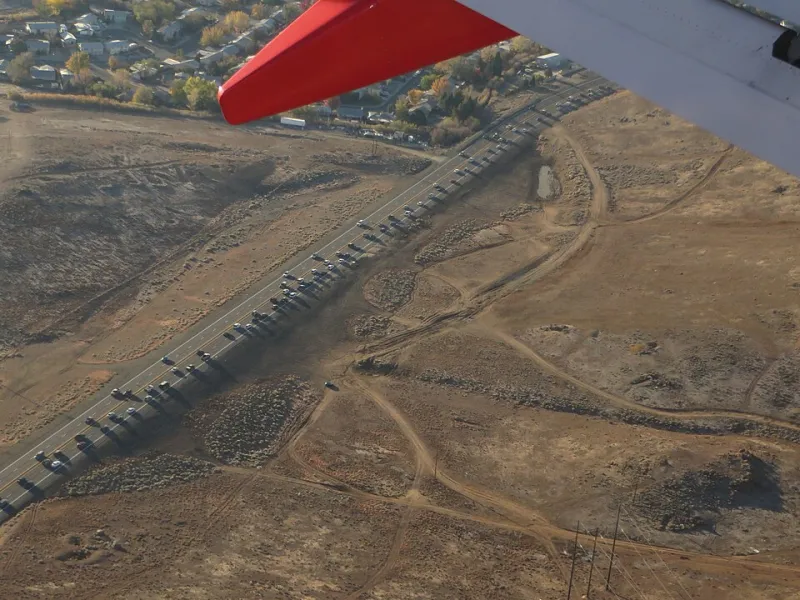
Photo: Ken Lund from Reno, Nevada, USA, CC BY-SA 2.0, via Wikimedia Commons
Every developer who has watched a product launch grind to a halt under a wall of authentication requests knows the feeling: the system didn't fail because it was broken. It failed because everyone showed up at once.
Mapping platforms solved this problem a long time ago. Navigation engines don't just react to congestion — they anticipate it. They know that the I-405 through Los Angeles will thicken at 7:40 a.m. on a Tuesday, that a Cowboys home game will choke the roads around Arlington hours before kickoff, and that a snowstorm in Denver reshapes the entire day's traffic graph. Your access infrastructure deserves the same foresight.
Congestion Is a Schedule, Not an Accident
The core insight from traffic modeling is that demand follows repeatable patterns. Rush hour isn't a surprise; it's a calendar entry. The same is true of credential systems.
Consider the load profile of a typical enterprise campus. Badge readers idle overnight, spike between 8:00 and 9:00 a.m., plateau through the day, and spike again at 5:00 p.m. A SaaS product's token endpoint does something similar: quiet evenings, a steep climb as East Coast teams log in, a second wave as the West Coast arrives. These are the commute patterns of your credentials.
The failure mode is always the same. Teams provision for the average and get crushed by the peak. Traffic engineers have a name for designing to the average: it's called a parking lot.
What the Mapping World Actually Does
Navigation platforms layer several predictive techniques, and each has a direct analogue in access management.
Historical baselines. Routing engines store months of segment-level speed data and compute typical travel times by day of week and hour. Your equivalent: instrument every authentication request, token refresh, and permission check with timestamps, then build hourly and daily profiles per endpoint and per region. Most teams discover their real peak is two to four times their average — a ratio traffic engineers would recognize immediately.
Event overlays. A stadium concert or a marathon doesn't show up in historical averages, so mapping products ingest event calendars and reweight predictions. Your analogue is the product launch, the quarterly all-hands that forces a thousand simultaneous SSO logins, or the seasonal hire class that provisions five hundred badges in one afternoon. If your access team knows about the event, your capacity plan should too.
Incident propagation. A single stalled truck on a highway doesn't cause one delay; it causes a cascade. Similarly, one slow upstream identity provider doesn't just delay one login — it queues every request behind it until timeouts cascade across services. Traffic models simulate this backpressure. Your load tests should too: inject latency into your IdP and watch where the queue forms.
Practical Provisioning: From Prediction to Policy
Prediction without action is just a dashboard. Here's how to convert traffic-style forecasts into concrete engineering decisions.
Pre-warm before the peak. Just as navigation apps route drivers around congestion before it forms, scale credential services ahead of known surges. If your forecast says Monday 8:00 a.m. is your heaviest window, autoscaling policies should begin adding capacity at 7:15, not 8:05. Token-signing services in particular benefit from warm caches of signing keys and pre-established database connections.
Meter the on-ramp. Freeways use metering lights to smooth the arrival rate. Rate limiting at your authentication edge serves the same purpose — but a flat limit is a blunt instrument. Shape limits by time of day and client class. A partner integration doing bulk token refreshes at 2:00 a.m. should face different constraints than interactive logins at 9:00 a.m.
Publish the forecast internally. Mapping platforms expose predicted travel times to their users; expose your predicted load windows to internal service owners. A team planning a mass credential rotation, for instance, should schedule it against the forecast, not against a hope. Rotating ten thousand API keys during the Tuesday login surge is the infrastructure equivalent of closing two lanes at rush hour.
Plan the detour. Every good routing engine offers alternatives. Your access stack needs them: a secondary identity provider path, a cached-verification mode for badge readers when the central service is unreachable, and a documented degraded-authentication policy that security has already signed off on. The detour only works if it was mapped before the incident.
The Stadium Test
The clearest stress test of these ideas comes from physical access. Venues that host events — arenas, convention centers, university campuses during move-in week — face the most extreme credential spikes in the industry. Twenty thousand people arriving within a ninety-minute window will expose every weakness in a badge system: reader throughput, network contention, slow directory lookups, help-desk queues for forgotten credentials.
The operators who handle it well treat it exactly like a traffic problem. They stagger entry gates, pre-issue credentials before arrival day, run load tests against projected turnstile throughput, and staff the failure points they can name in advance. The operators who handle it poorly find out at the gate, in front of the crowd.
Digital access systems face identical dynamics with higher stakes and less visibility. A stalled badge reader has a visible line; a saturated token endpoint just produces slow page loads and silent retries that make the problem worse.
Build the Graph Before You Need It
The mapping industry's deepest lesson isn't any single algorithm — it's that congestion is a property of the system, visible in advance to anyone who bothered to measure. Start with ninety days of request logs, bucket them by hour and endpoint, and overlay your known events: launches, rotations, hiring waves, seasonal peaks. You will likely find that your access infrastructure has a rush hour you never named.
Name it. Then provision for it. Your users shouldn't discover your capacity limits the same way commuters discover a closed lane — all at once, at the worst possible time, with everyone watching.